Greta Schmidt · 14 September 2026
Leveraging Analytics to Refine Tagging Systems in Digital Note Management Platforms
Digital note management platforms rely on tagging systems to organize vast amounts of information while users search and retrieve content efficiently across devices and teams. Analytics enter the picture when platforms collect data on how tags perform in real scenarios such as search frequency, click-through rates on tagged notes, and patterns of tag creation versus deletion. These metrics reveal gaps where tags fail to match user expectations or where overlapping labels create confusion during retrieval tasks.
Data Collection Methods in Tagging Environments
Platforms gather information through embedded tracking that logs every interaction with tags including additions, modifications, searches that return results, and instances where users abandon a query without clicking. Researchers at academic institutions have documented how aggregated datasets from millions of sessions highlight common pain points such as tags that grow stale over time or categories that users consistently bypass in favor of full-text search. By September 2026 several enterprise platforms reported expanded use of privacy-compliant pipelines that anonymize user behavior before feeding it into refinement algorithms.
Event logs combine with metadata like note creation dates, file types, and collaboration activity to build profiles of effective versus ineffective tags. One study from a European research consortium showed that tags applied during collaborative sessions receive higher reuse rates than those created in isolation because multiple contributors reinforce consistent terminology.
Analysis Techniques That Drive Tag Improvements
Machine learning models process the collected data to identify clusters of related notes that lack shared tags or to flag tags appearing in low-engagement notes. Clustering algorithms group similar content based on textual similarity and user navigation paths, then recommend new tag suggestions or merges of redundant labels. Platforms apply A/B testing frameworks where one group of users sees updated tag structures while another continues with the original setup, allowing direct comparison of retrieval speed and user satisfaction scores.
Statistical measures such as precision and recall evaluate how well tags surface relevant notes during searches. Data shows that iterative refinement cycles, repeated every few weeks, produce measurable lifts in these scores as outdated tags get archived and high-value terms rise in prominence. Industry reports from organizations focused on information management indicate that teams adopting analytics-driven tagging reduce average time spent locating notes by measurable percentages compared with static systems.
Implementation Examples Across Platforms
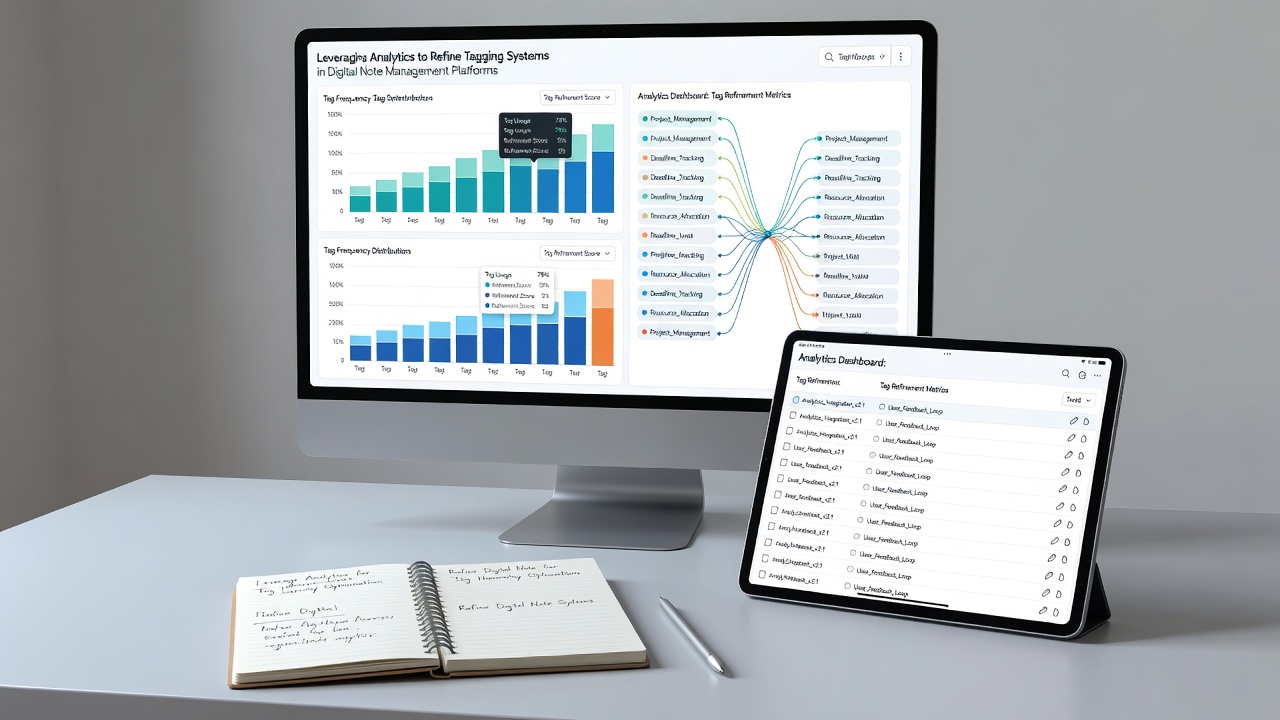
Observers note that productivity software vendors integrate these analytics into administrative dashboards where managers review heatmaps of tag usage across departments. In one documented rollout at a multinational firm, analysts discovered that project-specific tags outperformed broad thematic ones for cross-team retrieval, prompting a shift toward granular labeling conventions supported by automated suggestions. Academic sources including university-led examinations of knowledge work have tracked similar transitions in research groups that manage large literature databases.
Integration with external tools expands the reach of analytics because calendar entries, email threads, and shared documents feed additional context into tag recommendations. Government technology guidelines from agencies in Canada and Australia emphasize the importance of transparent data handling when platforms correlate activity across multiple applications to improve tagging accuracy.
Challenges in Scaling Analytics for Tagging
Volume of data presents ongoing hurdles because platforms must process interactions in near real time without degrading note-taking performance. Privacy regulations require careful segmentation of datasets so individual user patterns remain protected while aggregate trends inform system-wide changes. Technical teams address these constraints through edge computing that performs initial filtering on user devices before transmitting summarized statistics to central servers.
Tag evolution also introduces complexity since language shifts and new project terminology emerge continuously. Refinement processes therefore incorporate feedback loops where users can accept, reject, or modify suggested tags, and those explicit choices become additional training signals for future model iterations. Reports from trade associations in information technology sectors highlight that successful deployments maintain human oversight alongside automated processes to prevent drift in tag quality.
Conclusion
Analytics provide structured pathways for platforms to evolve tagging systems based on actual usage patterns rather than assumptions about organization needs. Through continuous collection, modeling, and testing, digital note environments achieve tighter alignment between how content gets labeled and how users seek it out. Ongoing developments in privacy-preserving computation and cross-platform data standards support further gains in retrieval efficiency while maintaining compliance across regions.